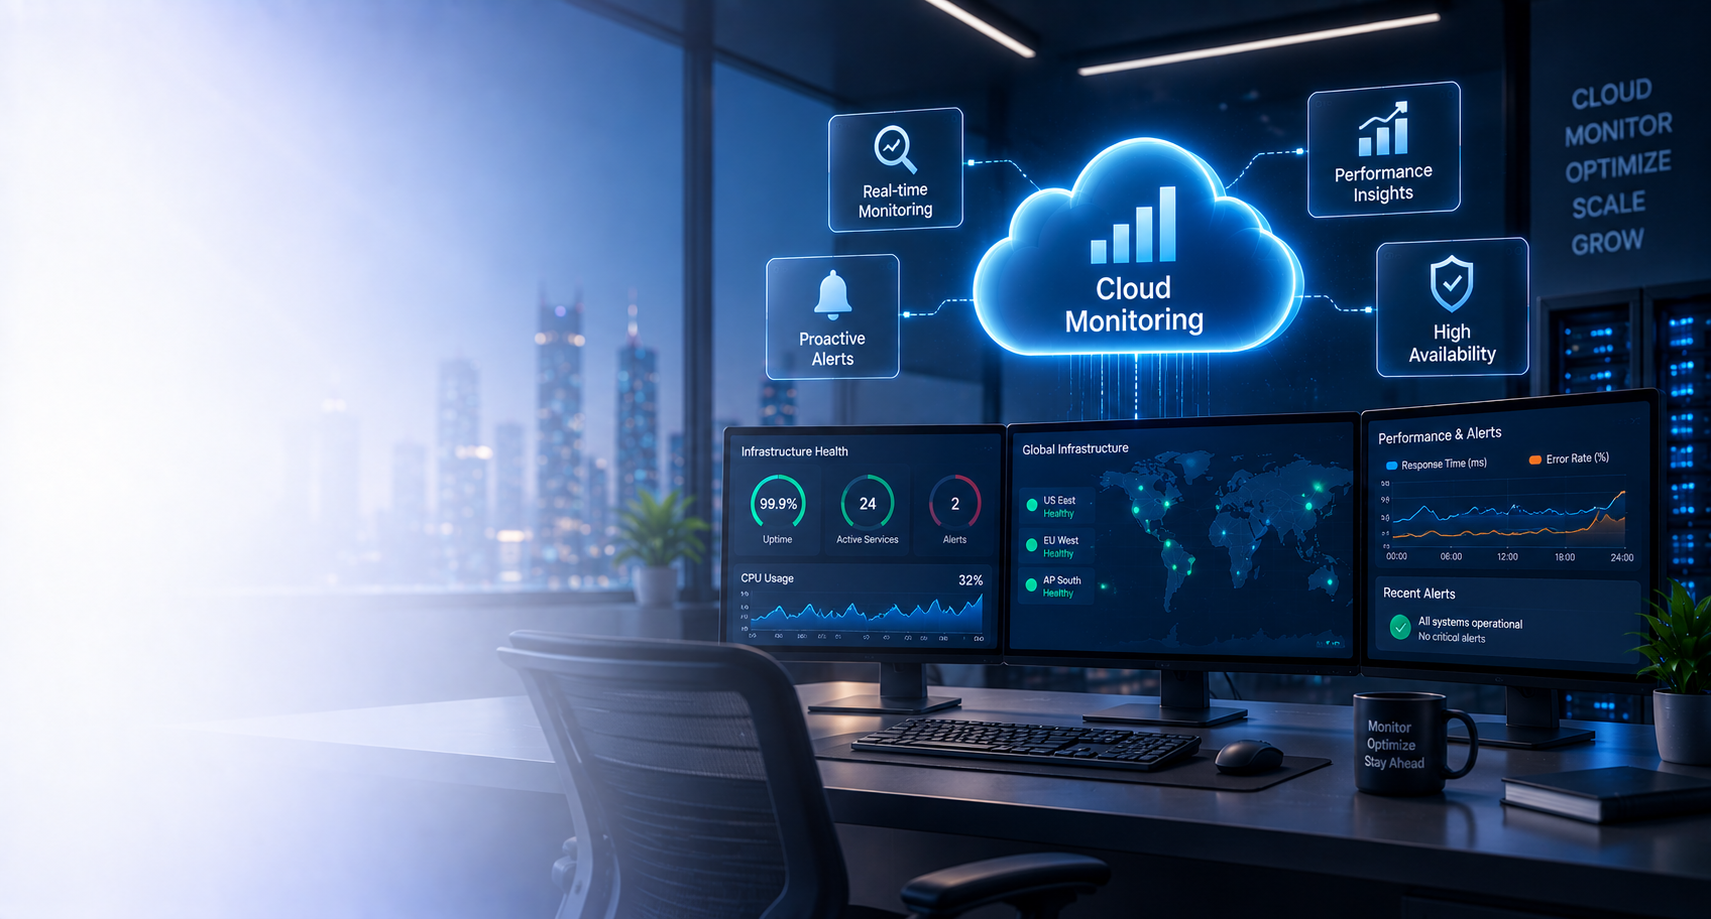
We provide continuous server monitoring — resource usage, service health, and uptime — with alerting so issues are caught and resolved quickly.
Without active monitoring, server issues are often discovered through user complaints rather than proactive alerts. We set up and manage continuous monitoring across your servers, so your team knows about problems while there is still time to act.
Monitoring only helps if the right things are watched and the alerts reach the right people. We focus on what actually matters for your servers, and on alerts worth waking up for.
CPU, memory, disk, and network usage tracked continuously.
Monitoring that key services and processes stay running.
Alerts configured to signal real issues, not routine noise.
Watching logs for errors and unusual patterns.
Alerts go out automatically around the clock; our engineers respond during business hours (Mon–Sat, 9:30 AM – 6:30 PM IST).
Clear reports on uptime, incidents, and resource trends.
We agree the exact checks for each server with you; this is what a typical setup covers:
Where it matters, we check that a system can actually do its job, not just that it is switched on. In one client engagement, monitoring set up after a server move now catches database failures in minutes instead of hours — read the case study. Monitoring tells you when something breaks; high availability architecture keeps the system running when it does.
This service covers servers: VPS, dedicated, on-premises and mixed providers, with ongoing management and reporting. For cloud-native services and their metrics on AWS, Azure or Google Cloud, see cloud monitoring.
A comprehensive suite of capabilities packaged into every engagement.
Configuring resource and service health monitoring across your servers.
Tuned alerts routed to the right people at the right severity, by email and WhatsApp.
Watching logs for errors and early signs of problems.
Responding to and resolving issues as monitoring flags them, during business hours.
Using the usage trends in the monthly report to flag disks and memory that are heading toward their limits, before they become incidents.
From deciding what to monitor to monthly reports on how your servers are doing.
Identifying what matters most to monitor for your specific servers.
Configuring checks, alert thresholds and who gets notified.
Automated checks around the clock, with incident response during business hours.
Reports on uptime, incidents, and resource usage trends.
Get a free consultation with our experts and a tailored proposal within 48 hours.